End-to-End Data Engineering & AI Pipeline
Metadata-driven Lakehouse automation with Databricks, Delta Lake, & Unity Catalog
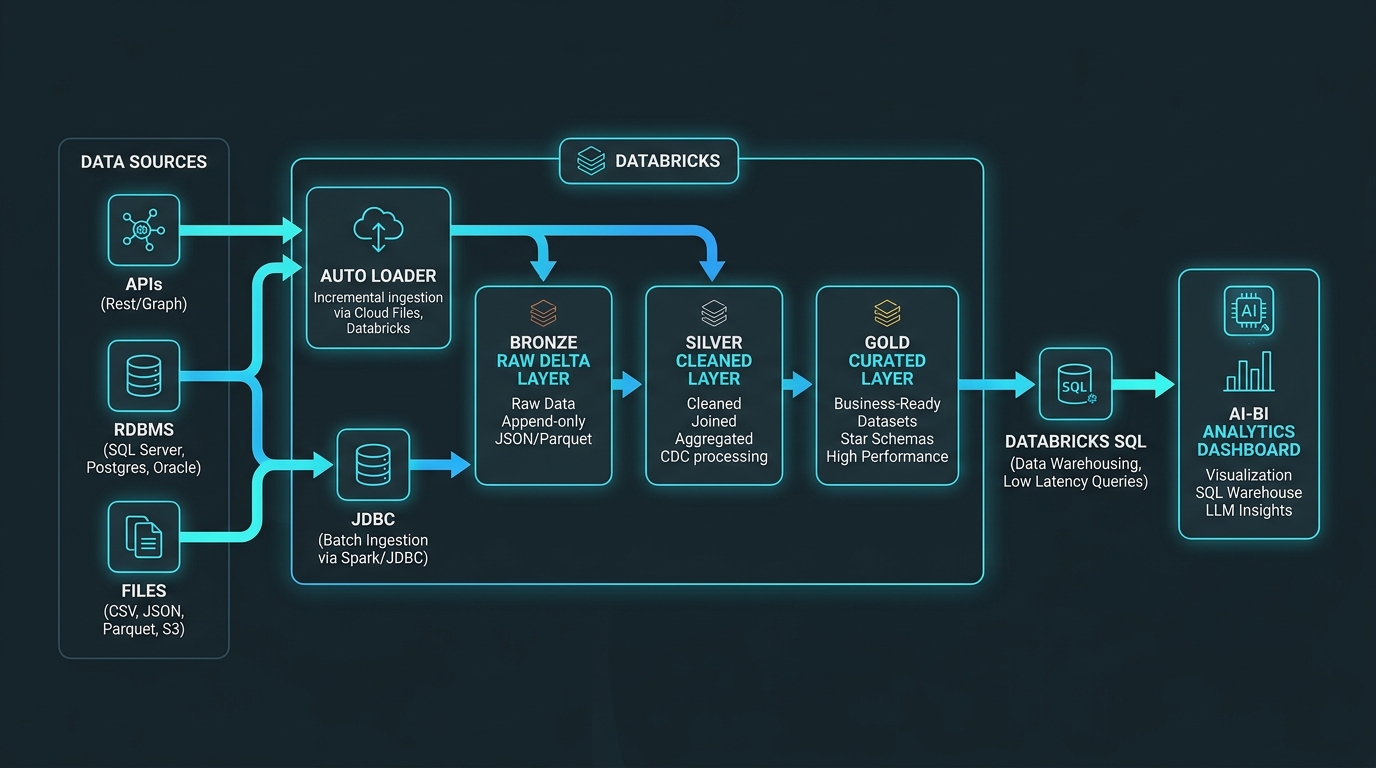
Project Overview
Built an end-to-end data platform that automates multi-source ingestion into a structured Lakehouse. Utilizing Databricks Auto Loader for file ingestion and JDBC connectors for relational databases, raw data is ingested into Bronze tables. PySpark scripts perform cleansing, validation, and deduplication into Silver tables, before business rules enrich Gold layer aggregate tables powering Databricks SQL dashboards and AI-BI analytics.
The Problem
Raw data arriving from heterogeneous sources (files and relational databases) suffered from inconsistent schemas and duplicate records, preventing downstream analysts from accessing timely datasets.
The Solution & Architecture
Architected a metadata-driven Medallion Lakehouse platform on Databricks with Auto Loader and JDBC ingestion, automated data validation rules, Delta Lake upserts via MERGE, and governance managed through Unity Catalog.
Key Engineering Highlights
Technologies Used
Interested in this Pipeline?
I can build similar production-grade Lakehouse or API data ingestion systems for your organization.
Contact Owais Ahmad