FMCG Data Engineering & Analytics Pipeline
Scalable sales, product, and customer analytics platform for FMCG data
Project Overview
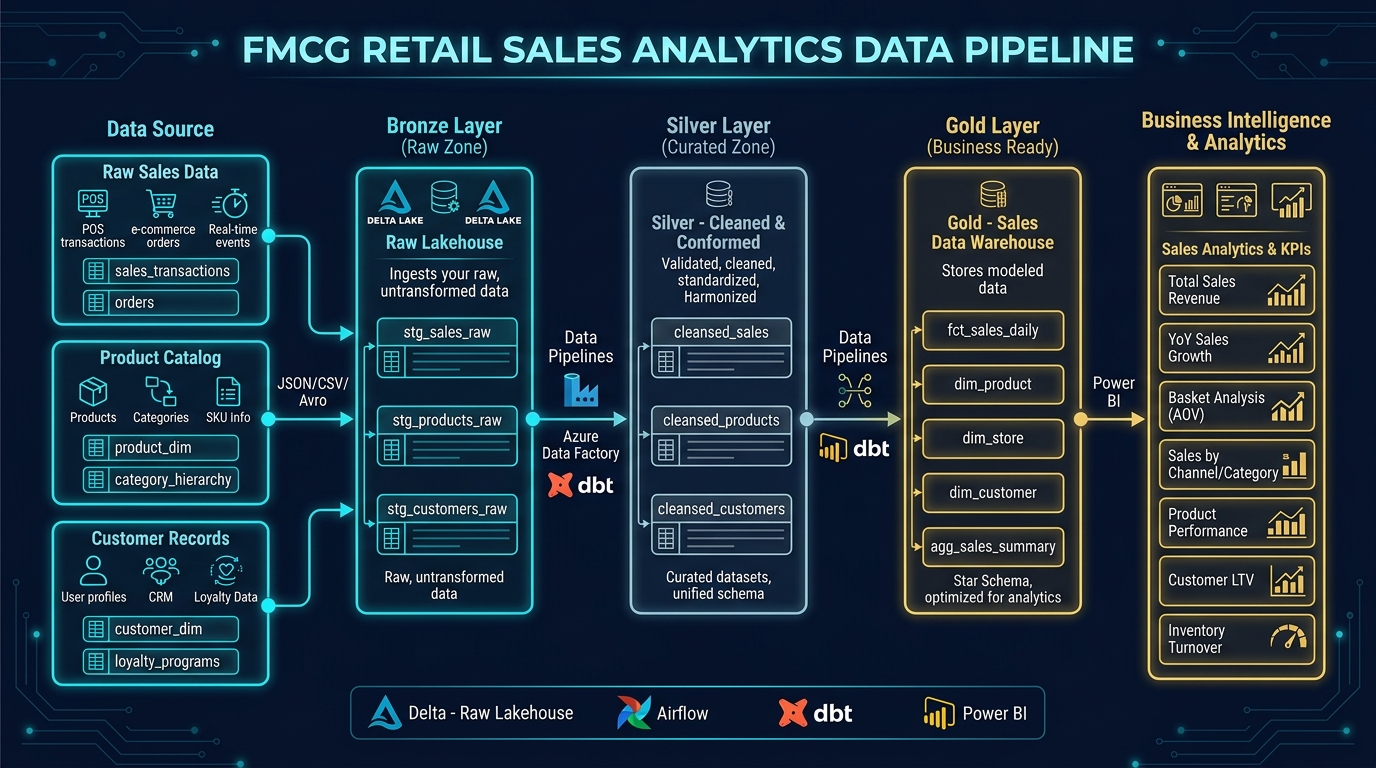
Designed and deployed a comprehensive FMCG data pipeline utilizing Databricks and PySpark to process fast-moving consumer goods transactions. The pipeline handles data profiling, cleansing, deduplication, and business-rule processing across Bronze, Silver, and Gold layers to produce metrics across sales performance, product turn rates, and customer purchasing patterns.
The Problem
FMCG business teams were unable to track sales KPIs or perform customer segmentation due to fragmented transaction logs and unvalidated product catalog entries.
The Solution & Architecture
Implemented a unified Delta Lake pipeline using Spark SQL and PySpark that ingests raw FMCG data, cleanses bad records, executes Delta MERGE incremental updates, and presents normalized sales and customer analytics in Databricks dashboards.
Key Engineering Highlights
Technologies Used
Interested in this Pipeline?
I can build similar production-grade Lakehouse or API data ingestion systems for your organization.
Contact Owais Ahmad